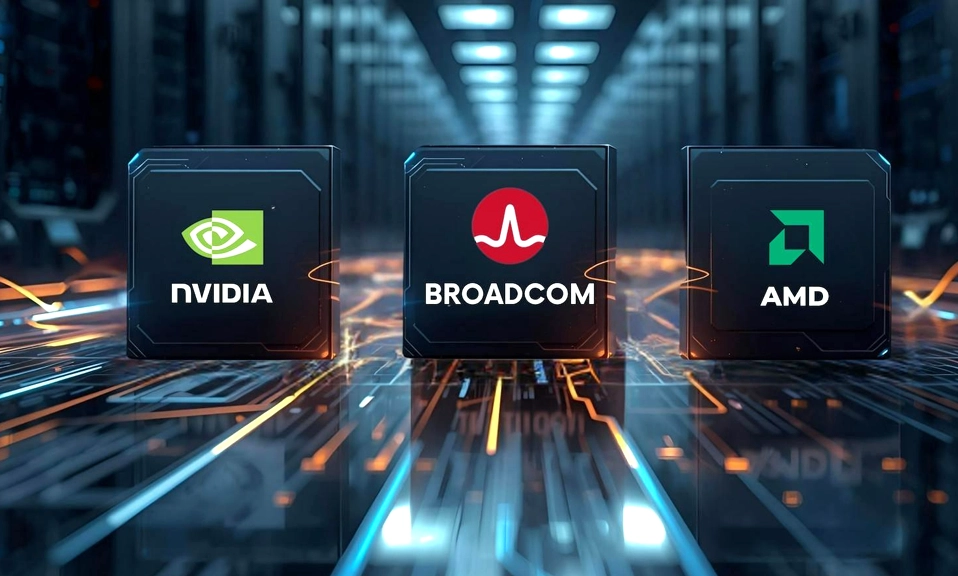
The AI chip market is no longer a one-horse race. For years, Nvidia’s dominance seemed unassailable, a fortress built on CUDA software and a relentless cadence of ever-more-powerful GPUs. In 2027, that fortress is still standing, but the ground beneath it is shifting. The AI infrastructure market has split into three distinct battlegrounds, and each is contested by a different champion. Nvidia remains the king of training, Broadcom is carving out a custom-silicon empire, and AMD is fighting to become a credible second platform. The question is no longer who will beat Nvidia. It is whether the AI chip market will ever be a single kingdom again.
The numbers tell the story of a market in transition. JPMorgan projects that global AI accelerator shipments will reach ~16.3 million units in 2026, and by 2027, the mix will flip: ASIC shipments will surpass GPUs for the first time, rising to 53% of the market from 42% in 2026. Nvidia’s share of AI accelerator shipments is projected to fall from 54% in 2026 to 41% in 2027, not because Nvidia is shrinking, but because the pie is expanding faster than any single company can serve. The battle for 2027 is a battle for the new layers of demand, and each contender is fighting on different terrain.
Nvidia: The Incumbent Defending a Fortress
Nvidia enters 2027 as the undisputed leader, but it is no longer the only game in town. Its data-center revenue reached $89 billion in its fiscal Q2 2026**, up **117% year-over-year**, and management has guided for **$1 trillion in AI chip revenue by CY2027. The company’s Rubin architecture is its next major weapon. The standard Rubin GPU is expected to ramp in the second half of 2026, followed by Rubin Ultra in the second half of 2027, which will feature four compute chiplets and 1TB of HBM4E memory. In a surprising move, Nvidia also revived its Rubin CPX, a specialized accelerator for the compute-bound “prefill” stage of inference. After being dropped from the roadmap, it is now scheduled for production in Q1 2027, equipped with 168GB of HBM4 and designed to pair with Rubin GPUs at a 1:1 ratio.
Nvidia’s greatest asset remains its software moat. CUDA is the default language of AI development, and its training market share is still effectively a monopoly. But that moat is being tested in inference. As the AI industry shifts from building models to running them, the priorities change from raw capability to cost, latency, and efficiency per token—terrain where custom silicon has a structural advantage. Nvidia is responding by expanding beyond the GPU. Its NVLink ecosystem, its Spectrum-X networking platforms, and its emerging agentic AI and physical AI ambitions are all attempts to make itself indispensable at the system level, not just the chip level. The strategy is to make Nvidia the platform, not just the processor.
Broadcom: The Custom-Silicon Juggernaut
If Nvidia is the incumbent, Broadcom is the insurgent—and it is the one Nvidia should be most worried about. Broadcom does not sell general-purpose GPUs. It designs custom ASICs for the hyperscalers who want to own their own silicon: Google’s TPUs, Meta’s MTIA, Microsoft’s Maia, and OpenAI’s Jalapeño. Its AI semiconductor revenue is on track to exceed $100 billion in fiscal 2027**, up from **$10.8 billion in the June quarter alone, and its AI revenue is projected to grow from ~$20 billion in FY2025 to $60 billion+ in FY2026 and $150 billion+ in FY2027.
The strategic logic is compelling. Custom ASICs strip out the general-purpose capabilities that a specific workload does not need, improving efficiency per watt and per dollar. For stable, high-volume inference workloads, they are simply cheaper. JPMorgan estimates that Broadcom holds 80-85% of the high-end custom ASIC market, and Counterpoint projects it will maintain ~60% share of AI server compute ASICs by 2027. The customer list is a who’s who of the AI infrastructure boom: Anthropic is deploying 1 GW of Broadcom-baked TPUs in 2026, scaling to 3 GW in 2027; Meta plans “multiple gigawatts” of XPUs in 2027 and beyond; and OpenAI is deploying ~1.3 GW of Jalapeño accelerators in 2027, with a pipeline of over 5 GW for 2028.
Broadcom’s rise is not a threat to Nvidia’s training business, but it is a direct challenge to Nvidia’s ambitions in inference. The custom-silicon approach is not a niche. It is becoming the default architecture for the hyperscalers’ most stable, high-volume workloads—the very workloads that will drive the next phase of AI spending.
AMD: The Challenger Fighting for a Second Platform
AMD is the third contender, and its position is the most uncertain. It has the products: the Instinct MI400 series is already shipping on TSMC’s 2nm process, with the MI500 series based on the CDNA 6 architecture expected in 2027. It has the customers: AMD has secured 6-8 gigawatt contracts with OpenAI, Meta, and Anthropic, and management has guided for data-center GPU revenue “far above” $30 billion in 2027**, with some analysts estimating **$40 billion+ in AI GPU revenue.
But AMD faces the same problem that has plagued it since the beginning of the AI boom: CUDA. Its software ecosystem, ROCm, is improving, but it is not CUDA. Every customer that switches to AMD must accept a period of retooling, retraining, and reduced productivity. AMD’s strategy is not to beat Nvidia on raw performance. It is to offer a credible second platform—a viable alternative that gives hyperscalers leverage, redundancy, and a way to negotiate prices. Its multi-gigawatt partnerships are evidence that this strategy is working, but its market share remains in the single digits, and its valuation has already priced in a lot of execution that has yet to be delivered.
AMD’s path to success is not displacing Nvidia. It is becoming too big to ignore—a genuine second source that captures a meaningful slice of the market as the AI infrastructure buildout continues to expand.
A Three-Way Split, Not a Single Winner
Who will dominate the next generation of AI chips? The honest answer is that no single company will dominate the way Nvidia dominated the last generation. The market is splitting into three layers, and each has a different leader.
Nvidia will remain the largest and most profitable player, anchored by its training monopoly, its system-level integration, and its relentless innovation cadence. But its share of total accelerator shipments will decline as the market expands and custom silicon takes root in inference. The 2027 Nvidia is not a declining giant. It is a company transitioning from monopoly to primacy—still the biggest, still the most important, but no longer the only option.
Broadcom is the biggest threat to Nvidia’s long-term pricing power. Its custom ASICs are not a fad. They are the logical architecture for the hyperscalers’ most stable, high-volume workloads, and Broadcom has locked in the customers and the order book to prove it. Its $100 billion AI revenue target for 2027 is not a projection. It is a line of sight.
AMD is the wildcard. It has the products, the partnerships, and the ambition. What it lacks is the software ecosystem and the market share to truly threaten Nvidia. Its success in 2027 will be measured not by how much share it takes from Nvidia, but by whether it can establish itself as a durable second platform—a position that would give it a permanent seat at the table.
The AI chip market of 2027 is not a zero-sum game. It is a market expanding so fast that all three companies can grow simultaneously, even as their relative shares shift. The question for investors, for customers, and for the industry is not who will win. It is how the value will be distributed across a market that is becoming larger, more diverse, and more strategically complex than anyone imagined just a few years ago. Nvidia built the kingdom. In 2027, the kingdom is being divided into duchies—and the dukes are not waiting for permission to rule their own lands.